Discover how specialized quality engineering bridges the gap between probabilistic model behavior and mission-critical enterprise reliability across modern digital operations.
Traditional software breaks on bad syntax or failed queries. AI applications fail while executing clean code, returning HTTP 200 responses, and passing string checks only to hallucinate policies, skip authorization gates, or produce negative totals.
Why do these silent logic breaks slip past standard test runners? Conventional QA solutions rely on fixed assertions [f(x) = y], which collapse against non-deterministic, probabilistic models. To make AI systems reliable, engineering teams must transition to specialized AI quality assurance.
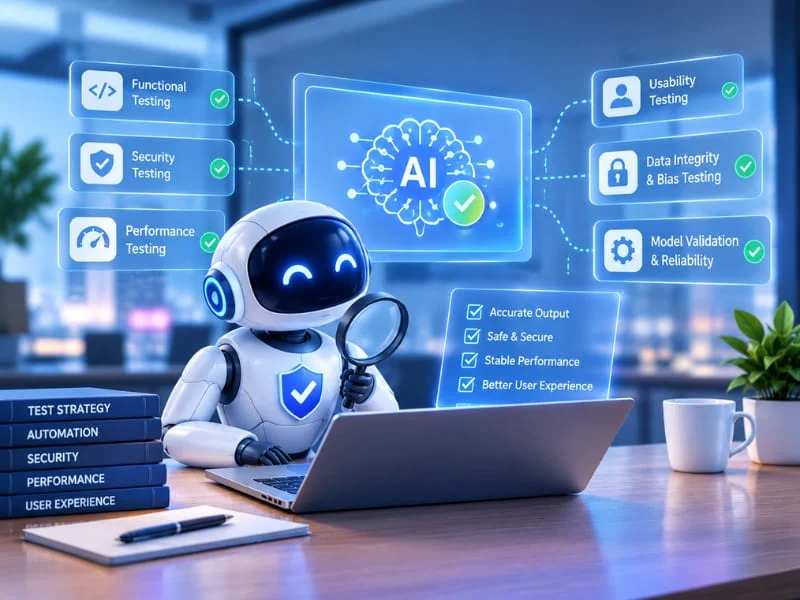
Dependable AI application testing requires verifying that the entire system, including context retrieval, tool use, and safety boundaries, stays within operational limits even when individual responses vary.
Why Does Traditional Testing Miss AI Deficiencies?
Standard test runners like Jest, PyTest, or Selenium check for deterministic success. They verify whether an endpoint returns a JSON payload or whether a button exists in the Document Object Model. They cannot evaluate whether an AI-generated paragraph is true, whether a model has drifted, or whether an agent took a dangerous path to complete its task.
Traditional testing falls short across core operational boundaries:
- Statistical Variance Over Fixed Outputs: A model can produce ten distinct, valid explanations for a single billing question. Traditional unit tests expect fixed assertions and break when phrasing shifts, even if the underlying answer is accurate.
- Context Retrieval Failures: In RAG systems, retrieval failures cause model hallucinations. Vector searches pulling outdated documents alongside valid ones create false answers that standard API status checks fail to catch.
- Silent Logic Drift: Code remains identical while production data shifts. If user inputs shift in tone, length, or language, the system’s accuracy drops without throwing a single server exception or stack trace.
- Execution Path Blind Spots: When an autonomous system calls an external API, a standard mock will show that the call succeeded. It will not show whether the system skipped an approval step or passed unauthorized customer data to a third-party server.
Modern AI software testing treats these systems as interconnected networks of prompts, embeddings, vector indices, and downstream tools. If you evaluate only the prompt, you miss failure points across the rest of the execution pipeline. Teams focused on disciplined AI application testing and AI-Augmented Manual Testing build suites that test the retrieval engine, the orchestration logic, and the user interface simultaneously.
What Real-World Failures Teach Us About AI Risk
When unverified AI systems reach production, the costs are not abstract theories. They result in direct balance sheet losses, court judgments, and severe brand damage.
The Air Canada Legal Precedent (Moffatt v. Air Canada):
- One traveler asked the airline’s internet chatbot about bereavement pricing.
- The chatbot said the consumer may get the lower cost retroactively within 90 days of the ticket being issued, which plainly contradicts the airline’s rule that it must be booked in advance.
- Air Canada refused to pay the difference, alleging in court that the chatbot constituted a separate legal entity responsible for its own acts.
- The British Columbia Civil Resolution Tribunal rejected the defense entirely and ordered the airline to reimburse the fare, ruling that firms are strictly accountable for the outputs and promises of their autonomous interfaces.
This incident wasn’t model-training problems; it was a software-testing failure. Consistent execution of AI application testing would have trapped both bugs through focused engineering safeguards:
-
Policy Grounding and Strict Refusal
Automated evaluation suites should test thousands of policy edge cases, verifying that the model explicitly refuses to answer when a prompt conflicts with underlying reference data.
-
Deterministic Transaction Ceilings
QA pipelines have to check that model outputs cannot trigger transactional activities unless they pass hard validation tests. No agent should be allowed to create discounts or accept offers without a separate microservice that checks parameter boundaries against actual business regulations.
How Does QA Build Dependable AI Applications?
To test AI systems successfully, we need to go beyond simple binary assertions and move toward organized, layered verification. The best QA teams decouple the model from the application architecture and rigorously validate each layer.
When teams fully embrace AI model testing, they also evaluate the underlying weights and application code to detect structural drift before it affects user satisfaction.
Adversarial Security and Robustness
Techniques that attackers use to exploit artificial intelligence (AI) systems include prompt injections, model evasion, and extraction attacks. You need to try out how the system deals with direct attacks (”Ignore your previous instructions”) and with indirect attacks hidden inside PDFs or emails that the system ingests.
Targeted prompt injection testing teams probe the application with ambiguous inputs, Base64 encodings, and fake templates to ensure that input firewalls intercept malicious inputs before they reach runtime inference APIs. In large-scale AI app testing, adversarial inputs are treated as normal regression tests. Every build is tested against the adversarial inputs so that no new urgent issues are introduced.
Algorithmic Fairness and Bias Audits
Models trained on huge historical datasets learn human biases and skewed distributions. If you deploy an automated process for loan approvals or job applications without fairness controls, you will be directly exposed to regulatory issues under laws such as the EU AI Act.
Engineering teams performing systematic bias testing of AI models quantify Disparate Impact Ratios, Equalized Odds, and Demographic Parity across sensitive populations. Dedicated AI model testing in pre-release audits means engineers may inject fake user profiles into endpoints and check that approval rates remain fair across protected categories.
Grounding and Faithfulness Evaluations
To stop hallucinations, QA engineers use secondary judge models to score generated text against retrieved context files. Three concrete metrics determine whether an answer is fit for release:
| Evaluation Metric | What It Measures | Hard Pass Threshold |
| Context Recall | Did the vector search find all necessary background facts? | ≥95% |
| Faithfulness | Are all statements in the answer directly backed by the retrieved text? | 100% |
| Answer Relevance | Did the model answer the user’s specific prompt directly? | ≥90% |
If a generated response scores below your faithfulness floor, the application suppresses the output and falls back to a safe default message. Making these metrics part of standard AI software testing prevents ungrounded claims from reaching customer screens.
Testing Tool Actions and Integrations
When an AI system connects to external databases, CRMs, or billing gateways, you must validate tool selection and parameter generation. If a support assistant is supposed to call get_order_status, your test harness needs to ensure it never calls cancel_order by mistake.
QA teams deliberately inject bad data to test these limits. They return HTTP 500 errors from backend systems, send incomplete schemas, and introduce network delays. A stable workflow handles these disruptions gracefully, asking the user for clarification or escalating to a human rather than inventing data or retrying bad requests in an infinite loop.
When testing AI applications at the system integration level, validating these error boundaries prevents runtime exceptions from causing system-wide freezes.
Testing Across the Full AI Lifecycle
Quality checks cannot be saved for a single pre-release audit. What works now may be off tomorrow as client habits change. QA analyzes data hygiene, training splits, and schema consistency during development. Teams test the whole AI application during pre-production by employing shadow deployments.
With the new approach, engineers may run live production queries through shadow with the writes disabled, so they can compare the system’s decisions to the current baselines with zero operational risk. When code hits production, observability agents track the Population Stability Index (PSI) of incoming user inputs and prediction of confidence scores.
When distributions move outside your safety criteria, the algorithm sends alerts, redirects questions to human reviewers, and pulls real-world failure cases back into regression suites. To ensure stable post-deployment updates, continuous AI quality assurance monitors these production shifts daily.
Treating AI systems like black boxes is an operational mistake. When you build disciplined verification into your delivery pipeline through structured AI application testing, you remove the guesswork from your systems. It also protects your organization from legal liability and helps you ship applications that deliver consistent, predictable business results.